ContentsStart0%
TypeSafe AI opened early access to Jev on September 15, 2026, positioning it as a “System One Model” for fast, structured decisions. Instead of writing an article, Jev takes a state and predefined questions, then returns choices, scores or probabilities that software can use.
The original article was published on September 20 and later included October product and funding updates. This adaptation retains that sequence and distinguishes vendor descriptions, a public SEO demonstration and independent validation.
What does “System One” mean in this product?
TypeSafe borrows the name from the distinction between fast, intuitive System 1 and slower, deliberative System 2 associated with Daniel Kahneman. It positions Jev for many narrowly specified judgments that an application combines into a workflow. The model name refers to economist William Stanley Jevons, echoing the idea that cheaper decisions can expand demand.
A typical task could classify a page by topic, evaluate whether two pages are related, or route an incoming record. The acceptable answer space is defined before the call, rather than left as an unrestricted text response.
DCVC’s September 15 announcement described a US$40 million seed round for the San Francisco company. In a subsequent October 9 post, TypeSafe announced US$870 million in Series A funding at a US$7.5 billion valuation, led by Andreessen Horowitz with Sequoia Capital and DCVC participating. Financing is company context, not evidence that a model’s decisions are correct.
How is Jev different from a general-purpose language model?
A language model can produce prose, code or structured output. Jev gives up unrestricted text generation and focuses on a constrained decision interface. The meaningful difference is its design and response types, not a claim that ordinary LLMs cannot return JSON.
| Type | Question | How software can use it |
|---|---|---|
| Choice | Which predefined option fits? | Classify a page or route a record; inspect probabilities and confidence. |
| Score | Where does this state fall on a defined rubric? | Prioritize a review queue using a consistent scale. |
| Noul | How likely is this statement to be true? | Use a 0–1 probability with an explicitly chosen threshold. |
The official quick start describes sending a state and several questions in one call. A content record can therefore be assessed for topic, intent and a relevance condition within the same request.
Type safety limits the output’s form. It does not make the underlying classification infallible, and a confidence score should not be treated as independently proven calibration on the user’s dataset. A low-cost typed answer still needs evaluation against labeled examples and appropriate review.
What did the 500-review demonstration show?
The original article included a demonstration classifying the sentiment of 500 restaurant reviews. Its displayed results were:
| Model | Elapsed time | Displayed accuracy | Estimated cost |
|---|---|---|---|
| Jev | 63.1 seconds | 88.8% | US$0.1892 |
| DeepSeek | 494.2 seconds | 85.2% | US$0.4534 |
Within the demonstration, Jev was faster, cheaper by the displayed estimates and somewhat more accurate. The available clip does not establish a general speed ratio or a complete reproducibility protocol for prompts, model versions, concurrency and labeling. Treat it as a concrete demonstration of the use case rather than a universal model ranking.
The Chinese workflow images are replaced with this explanation: a prose workflow asks a model to answer, then interprets and validates the answer before acting; a typed workflow defines possible decisions first, receives constrained values and passes them to explicit downstream logic. Both need validation of the decision itself.
The 586-page internal-link case
SEO practitioner Borja Obeso reported a Jev demonstration processing 586 pages in 45.1 seconds, placing 584 internal links at a total cost of about US$0.21. Dividing the stated cost by the page count gives approximately US$0.36 per 1,000 pages. That is a normalization of this example, not an observed price for every thousand-page site.
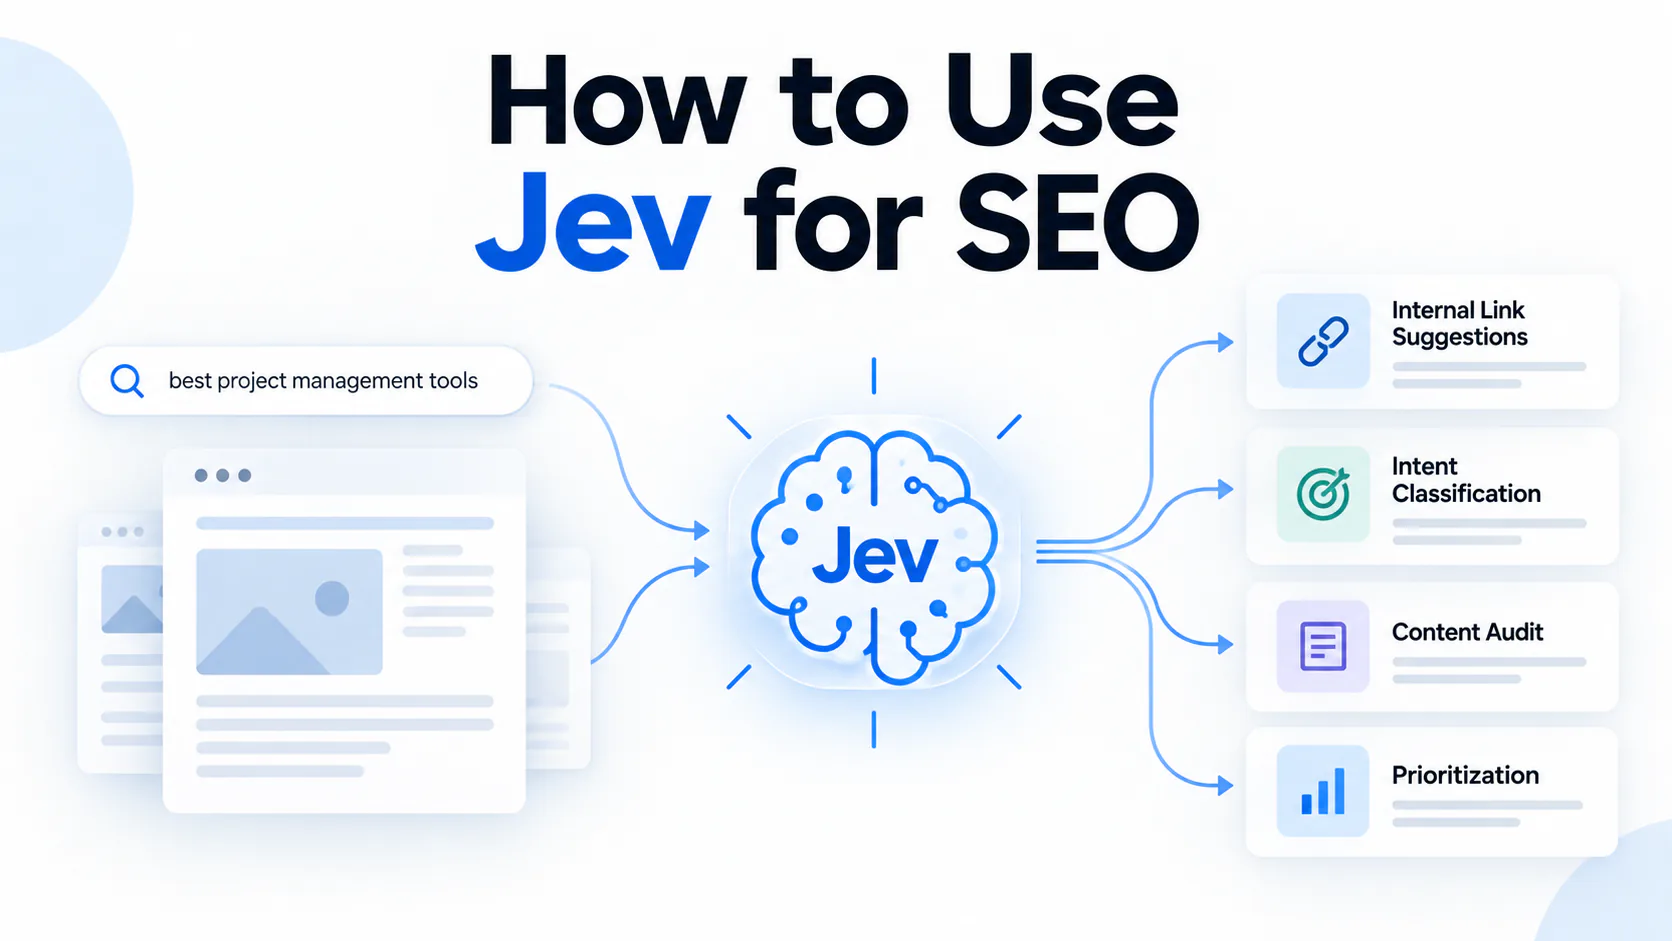
The useful idea is to break linking into explicit decisions: do two pages have a meaningful relationship, does a passage contain suitable anchor text, and is the proposed destination appropriate? A crawler can enumerate URLs and links, but those semantic checks are different work.
The demonstration does not prove every inserted link improved the site, increased traffic or was editorially correct. A production workflow should retain the source page, proposed link, reason and review state before applying edits.
Other plausible tasks include classifying search intent, assigning topics, flagging overlapping pages and prioritizing a content inventory. These are designs inferred from the interface, not new production results measured here. At a different layer, OpenSEO supplies data and tools to agents rather than serving as the decision model.
How the documented access flow works
Use the official TypeSafe site, documentation and console. A similarly titled Jev site on another domain should not be assumed to be the vendor or a safe place to enter a vendor API key.
The original September update recorded TypeSafe removing the waitlist on September 20. That is a dated access announcement; current onboarding should be checked in the console.
The documentation offers Python or JavaScript SDKs, a direct API, an agent skill and a browser Playground. With the skill route, the original instruction was:
npx skills add typesafe-ai/skills --skill typesafe-aiThis command explains the documented integration and was not executed for the adaptation. It installs software, a different action from reading the news. Keep keys in environment variables or a secret manager and check the official instructions before using it.
A testable task might say: classify an inventory into an agreed list of intents, return the label and uncertainty, and leave the site unchanged pending review. That is clearer than asking a system to “optimize the site.”
Pricing, model versions and limits
The September launch post quoted US$0.042 per million input tokens, equivalent to US$42 per billion, with no output charge. The model documentation rechecked for this adaptation lists the same price for Jev 1.13 and 1.14, identifying 1.14 as an October 14 release. Billing depends on actual input and account terms.
The original coverage recorded a maximum of 255 options for a Choice question. Tasks requiring extensive reasoning may need decomposition into smaller decisions and explicit program logic. Neither this architecture nor a low token price makes Jev a prose-writing or general conversation product.
TypeSafe acknowledged in its launch discussion that long-term operations would have to demonstrate the economics behind the price. A small demonstration cannot settle that business question.
How to judge whether Jev fits an SEO workflow
Start with a decision an editor can define and label consistently. Compare outputs with those labels, inspect disagreements and measure the cost of reviewing uncertain cases. Time saved in a model call can disappear if a poor rubric produces unusable classifications.
For internal links, correctness means more than choosing a valid URL: the destination must support the surrounding passage and help the reader. For overlap detection, similarity alone does not justify merging pages with different intent. A typed model can prepare a review queue while a website change remains a separate approved step.
The relevant result is a reliable completed workflow with a known review burden. The schema, demonstrations and token price inform that decision, but none alone proves it.